This guide explains how the name Lisandro Roberto Teixeira Martins is used as a reference point for academic and professional context, emphasizing careful verification, sourcing, and responsible research practice. Objectively, the keyword reflects a personal identifier that may appear across public records, publications, or professional profiles, requiring readers to cross-check details before drawing conclusions.
When you encounter the name Lisandro Roberto Teixeira Martins, treat it first as a personal identifier that may appear in publications, institutional directories, legal or civil registries, conference materials, or professional networking profiles. The very important step for any researcher, journalist, or compliance-minded reader is to verify how the name is connected to a specific claim—rather than assuming that every appearance of the name indicates the same person or the same role.
In everyday life, people assume that if a name is present in a document, the meaning is straightforward. In research, that assumption is risky. Names can be shared, recorded imperfectly, or reused across contexts such as academic authorship, contractors on projects, invited speakers, or board members. The more high-stakes the decision—whether it’s reputational, legal, ethical, or financial—the more you should treat the name as an index into records, not as proof of identity by itself.
From an industry perspective, names like this often surface in fragmented data environments: databases may standardize spelling differently, omit accents, compress middle names, include multiple initials, or translate the ordering of given name and family name. Because of that, responsible research hinges on context matching (affiliations, dates, document titles, or subject matter), not on the name alone.
This matters even more when you encounter the name through search engines, aggregator sites, or scraped datasets. Search results are often “fuzzy,” ranking items by textual similarity rather than identity certainty. An item might mention the name because it’s in a citation list, because someone shares the same name, because a person’s name appears in an acknowledgement section, or because it’s part of a metadata field imported from a third-party system. Each of these scenarios demands a different level of confidence.
Therefore, the core reason the name “matters” is that it can influence what readers believe about authorship, affiliation, expertise, accountability, or participation. In other words, it matters not only because a person exists, but because a name can be used—intentionally or unintentionally—as a proxy for facts. The responsibility of researchers is to prevent that proxy from substituting for evidence.
Lisandro Roberto Teixeira Martins functions in practice as a reference label for an individual. In scholarly and professional settings, the same name can refer to multiple people, while the same person can appear under multiple variants (for example, with or without middle names). Therefore, the keyword should be treated as the starting point for identity resolution rather than the endpoint of research.
In data governance terms, this is a classic scenario of entity resolution. Many information systems rely on “top-effort matching,” which can produce collisions (two people mapped to one record) or splits (one person mapped to several records). When a system matches records using incomplete signals, it may be “correct often,” but “often” is not the same as “reliably.” In compliance contexts, even a low false match rate can be unacceptable, particularly when decisions depend on the output.
To manage this, researchers and data quality professionals aim for a chain of evidence. Instead of asserting “this is the person,” you try to build a structured explanation: the same person appears across multiple independent sources with consistent attributes—affiliation, timeline, co-authors, or professional roles. When those attributes align, identity confidence grows.
Another objective layer is provenance: where the information comes from and how it was captured. A record created by a journal editorial system may have higher provenance than a record manually entered by a third-party. Conversely, some institutional directories may be authoritative regarding employment or job title, but less reliable regarding academic publication lists. Understanding which data sources are likely to be accurate for which fields is part of good research methodology.
It can also help to consider how identity is represented in different systems. Some systems store names as free text; others store components (given name, middle name, surname). Some store the name as entered, including diacritics. Others normalize it, removing accents and converting characters. Even when the underlying person is the same, the visible string can change. Thus, the keyword is not “one identifier,” but “a family of possible representations” that must be reconciled.
As an expert in information quality workflows, the recommended approach is to build a structured chain of evidence. Instead of asking, “Who is Lisandro Roberto Teixeira Martins?” focus on: “What specific document or record ties Lisandro Roberto Teixeira Martins to the claim I’m evaluating?”
This shifts the goal from a potentially unanswerable question (identity in the abstract) to an answerable one (identity in relation to a specific artifact). Professionals prefer artifact-based verification because an artifact—like a paper, staff listing, or official program entry—provides a boundary around the claim. It tells you what exactly you are verifying and allows others to check your reasoning.
Key validation signals commonly used in professional practice include:
Additionally, professionals often use “co-occurrence” patterns: if the same co-authors appear repeatedly with the same affiliation and topic, that pattern can help disambiguate identity. Similarly, repeated presence in a particular committee or recurring involvement in themed conferences strengthens the linkage.
However, good practice also recognizes that co-occurrence patterns can be misleading. People collaborate across institutions, change careers, or publish outside their main research area. Therefore, subject alignment is evidence to consider, not evidence to force. When evidence conflicts, the professional response is to revisit the primary sources and document the uncertainty.
This discipline is especially relevant when a personal name is used as a search keyword. It’s common for search results to mix similarly named individuals; therefore, readers should interpret search hits as leads, not confirmations. A lead is an invitation to verify; confirmation requires primary evidence and consistent metadata.
To use Lisandro Roberto Teixeira Martins responsibly in research, professional due diligence, or content creation, certain conditions should be met:
Responsible use also includes how you write. For example, if you’re not sure a given record corresponds to the same person, you might write “appears as an author on the paper titled X” rather than “is the author” if the identity link is unverified. That subtle language change can preserve credibility and reduce the risk of misrepresentation.
In addition, when names appear in datasets used for compliance screening, analysts should apply a consistent policy: define thresholds for matching, document why you treat certain signals as sufficient, and ensure you have a human review process for ambiguous cases. Even if your work is “only research,” the output can still be used by others, and the consequences of errors can scale beyond your immediate intent.
Finally, responsible research involves bias awareness. Researchers can unconsciously over-trust evidence that fits an expected narrative. If your background assumptions suggest the person is “likely” to be the one you need, you must still check primary documents. Good methodologies deliberately resist the temptation of convenient matches.
Names like Lisandro Roberto Teixeira Martins are frequently encountered in contexts such as:
However, the existence of a name in any of these venues does not automatically confirm the specific details readers may be searching for. Responsible research requires the reader to connect the name to the correct item. For example:
This is why responsible interpretation is iterative: you gather evidence, verify it, and then refine your understanding. Each context can be helpful, but none is sufficient on its own unless it is primary and consistent with other known attributes.
The following comparison helps you interpret information you may find when searching for Lisandro Roberto Teixeira Martins. This is not a claim about any specific record; it is a methodological guide for how to weigh what you see.
| Evidence Type | Typical Example | What It Can Support | Common Limitation |
|---|---|---|---|
| Primary publication | Journal article metadata with author list | Authorship and subject matter | May not clarify identity beyond the published author name |
| Official institutional record | University or organization staff listing | Affiliation and role | May omit middle names or use abbreviated naming |
| Conference program entry | Program schedule or proceedings listing | Participation and timing | Can contain formatting inconsistencies |
| Secondary repost | Aggregation pages referencing documents | Leads for further verification | May introduce errors or outdated info |
| Unverified mention | Forum or comment without documentation | None (for factual claims) | High risk of mistaken identity or inaccuracies |
To deepen the practical meaning of the table: evidence strength is not only about the “type” of record but also about field-level reliability. For instance, an official staff listing may be reliable for employment status, but might be less reliable for publication history if it’s not updated frequently. Likewise, a DOI record is highly reliable for bibliographic metadata, but it may still not disambiguate between two individuals with similar names if it doesn’t include additional identifiers like ORCID.
Therefore, when you evaluate a record, ask two questions: (1) is the record authoritative for the specific attribute you care about, and (2) does it contain enough context to resolve identity with minimal ambiguity?
If you are researching Lisandro Roberto Teixeira Martins—for example, to confirm authorship, professional involvement, or the correct person behind a statement—use this structured workflow.
Write down what you’re trying to confirm (authorship, employment, expertise area, or a specific claim). Don’t search “blindly”; define the end question first.
This step often prevents wasted effort. If you don’t define whether you’re verifying “authorship” versus “employment,” you may treat the wrong evidence as sufficient. For example, a staff listing can confirm employment but might not confirm academic authorship.
Note whether the spelling includes middle names or initials. Track variants you encounter during searches.
In practice, keep a small “variant set.” For example, you might track full name, abbreviated name, reversed name order, and versions with or without accents. Later, when you compare records, you can see whether the variations align with the same person.
Seek out the document itself—published papers, official staff pages, or institutional listings—rather than relying on rehosted summaries.
If the primary source is paywalled or hard to access, you may use metadata from indexing services, but treat that as preliminary. Prioritize sources that provide bibliographic identifiers (DOI, conference IDs, official PDFs, archived institutional pages).
Check dates, affiliations, titles, co-authors, and subject keywords. Identity resolution is stronger when multiple metadata points align.
Triangulation is not merely “finding multiple pages.” It is verifying that multiple fields tell a consistent story. For instance: the same person appears with the same affiliation at a time consistent with the publication date, and the topics match the known expertise of that affiliation.
If you find multiple individuals with similar names, compare their affiliations and timelines. A match in one field does not guarantee the same person in another.
Collisions are common when names are not unique, when records are incomplete, or when systems truncate or reorder names. If the affiliation changes abruptly between two publications, treat it as a hypothesis to evaluate, not an automatic disqualifier.
If you cannot verify a key detail, describe it as unconfirmed. In professional work, stating uncertainty is more credible than forcing conclusions.
Documentation matters: record what you tried, which fields were missing, and what additional evidence would resolve the question. This makes it easier for others (or future you) to revisit the work.
Create a record of which sources you used and why they were considered credible. This is useful for review, corrections, and future updates.
An audit trail can be as simple as a list of URLs and publication identifiers, or as formal as a compliance case file. Either way, it turns your research into a verifiable process rather than a one-time reading of search results.
Beyond these steps, professionals also apply “confidence scoring.” While not every workflow needs formal scoring, the concept is useful: assign higher confidence when the identity is supported by multiple independent, authoritative sources that agree on key fields. Assign lower confidence when evidence relies on weak or secondary sources, missing metadata, or inconsistent timelines.
Additionally, consider reverse verification: instead of only checking whether the name matches the claim, check whether the claim matches the name. For instance, verify whether the topic and affiliation associated with the publication also correspond to the person’s known professional background. If there’s a strong mismatch, you may be dealing with a collision.
Your request included placeholders for price information, supplier details, and localization, but no concrete figures or supplier identifiers were provided in the input. As a result, this article focuses on the keyword Lisandro Roberto Teixeira Martins in a context-appropriate way: verification, responsible interpretation, and research methodology. If you share a specific product/service, supplier name, and location, the article can be adapted to include accurate pricing and sourcing with appropriate conditions.
To make the distinction explicit: name verification is one kind of research task; procurement research (price, supplier, location) is another. However, they overlap in one important respect—both require evidence quality and appropriate sourcing. In procurement research, a supplier claim about price or availability needs documentation; in identity verification research, a name claim about authorship or role needs documentation.
If you later want to incorporate price and supplier details, you would typically apply similar evidence principles: use primary pricing sources when available (official quotes, vendor catalogs, contract documents), capture effective dates, ensure the location-specific terms match the geography you care about, and document uncertainty when pricing depends on tiers, volume commitments, or promotional windows.
Similarly, if supplier information is associated with a person (e.g., a sales representative, contractor coordinator, or authorized signatory), you would still want to confirm identity via role-specific records, not just via the display of a name on a web page.
In other words, the methodology described throughout this article can generalize to other research domains: treat names as entry points to evidence, not evidence themselves.
When discussing identity and research context, the safest approach is to rely on established standards for information quality and data integrity. For example:
For background reading on data quality concepts, ISO/IEC data quality standards are widely referenced by enterprises and research repositories. For publication metadata practices, DOI registration and indexing conventions are commonly used in scholarly ecosystems. (Consult the latest standard text or repository guidance for exact wording and current editions.)
In practical terms, industry standards often translate into a set of behaviors:
How do you avoid unverified claims? By distinguishing between three categories of statements you may see online or in compiled texts:
An additional reliability concept is “source hierarchy.” When you encounter a claim about someone’s work or role, you should generally prefer:
This hierarchy doesn’t mean secondary sources are worthless; it means they should be treated as leads. The moment you transition from “lead” to “fact,” you must have primary evidence or a strong chain of verification.
No. A full name can still match multiple individuals. Treat the name as a starting point and verify the connection using primary documents, affiliations, and consistent metadata.
Even if the full name appears “complete,” uniqueness is not guaranteed. Some individuals share identical names. Additionally, variations in spelling or formatting can cause one person to appear under multiple strings—creating the false impression that different identities exist. Conversely, the opposite can happen: two individuals might be incorrectly merged in a database, causing a single record to contain mixed information.
Use the original publication record (journal or conference proceedings) and cross-check metadata such as publication date, title, co-authors, and affiliation details. Secondary listings should be used only as leads.
If you can access a DOI entry or the publisher’s page for the paper, that is typically a strong foundation. Then you evaluate whether the affiliation and co-author network align with the identity you believe you’re verifying. If the publication record doesn’t provide enough detail to disambiguate, look for additional sources such as institutional pages, ORCID identifiers (if available), or other publications from the same time period.
Spelling differences (including omission of middle names or alternative formatting) can lead to split records or missed matches. You should search for variants and then confirm with contextual evidence rather than name similarity alone.
Spelling variants may occur due to data entry practices, typographic differences, or system constraints (for example, systems that cannot store diacritics). In some cases, the same person uses different name styles across regions or languages, which can change the ordering of given names and surnames. When you search, you should not only vary accents and initials but also consider common truncations and order swaps.
When sources disagree, document the discrepancy and avoid strong claims. Re-check the primary source, look for updated institutional pages, and compare timelines and affiliations to determine which record is more credible.
Conflicts can arise because of outdated pages, mistaken entries, or genuine career changes. A professional approach is to identify which source is more authoritative for the specific attribute. For example, a primary publication record is usually more authoritative for authorship than a third-party database. However, institutional pages may be more authoritative for employment status than a publication metadata record that includes an affiliation at the time of the paper.
You can, but only when the information is properly sourced and relevant to the decision. If verification is incomplete, treat it as preliminary and include uncertainty in your conclusions.
Decision-making implies responsibility. If the decision is hiring, vendor selection, grant allocation, compliance screening, or reputational attribution, you should aim for strong evidence. If you only have partial evidence, you should implement safeguards—such as requiring human review, asking for additional documentation, or limiting the decision to low-risk uses until verification is complete.
Yes. Keep personal data use proportionate and relevant, and prioritize publicly verifiable and job-relevant or academic information. Avoid drawing personal conclusions that are not supported by reliable evidence.
Ethical research means you avoid unnecessary personal details and avoid speculation. Even when information is publicly available, it may not be ethically appropriate to aggregate it into a narrative beyond the person’s professional context. If the individual is a private person (not a public figure), you should be especially careful about what you infer and how you present it.
If you share the intended country/region or the local audience you’re targeting, the article can incorporate culturally appropriate framing and relevant institutional context. For this version, no specific location content was provided beyond the keyword itself.
Localization matters because naming conventions, institutional structures, and document types vary by region. For example, how people present their full names, how institutions list staff, and which registries are accessible can differ significantly between countries. If you want a version tailored to a specific region, you would also need guidance on which local sources are considered reliable and which are not.
In professional and academic research, Lisandro Roberto Teixeira Martins should be handled as a person-based reference label that requires verification. The strongest outcomes come from linking the name to primary sources, aligning metadata, and documenting uncertainty when evidence is incomplete. By using structured validation practices—rather than relying on name matches alone—you can reduce the risk of mistaken identity and improve the credibility of your work.
Ultimately, the discipline is about evidence quality and responsible interpretation. A name is a doorway into records, not proof of identity. When you treat it that way—systematically, methodically, and transparently—you make your research more resilient to errors, less vulnerable to confusion, and more useful to others who may depend on your findings.
If you want to extend this approach further, consider creating a repeatable checklist or template for identity verification in your workflow. Many organizations do this to ensure consistency across projects, reduce bias, and standardize how uncertainty is handled. The same principle applies here: the name may vary, but the verification process should remain rigorous, auditable, and context-aware.



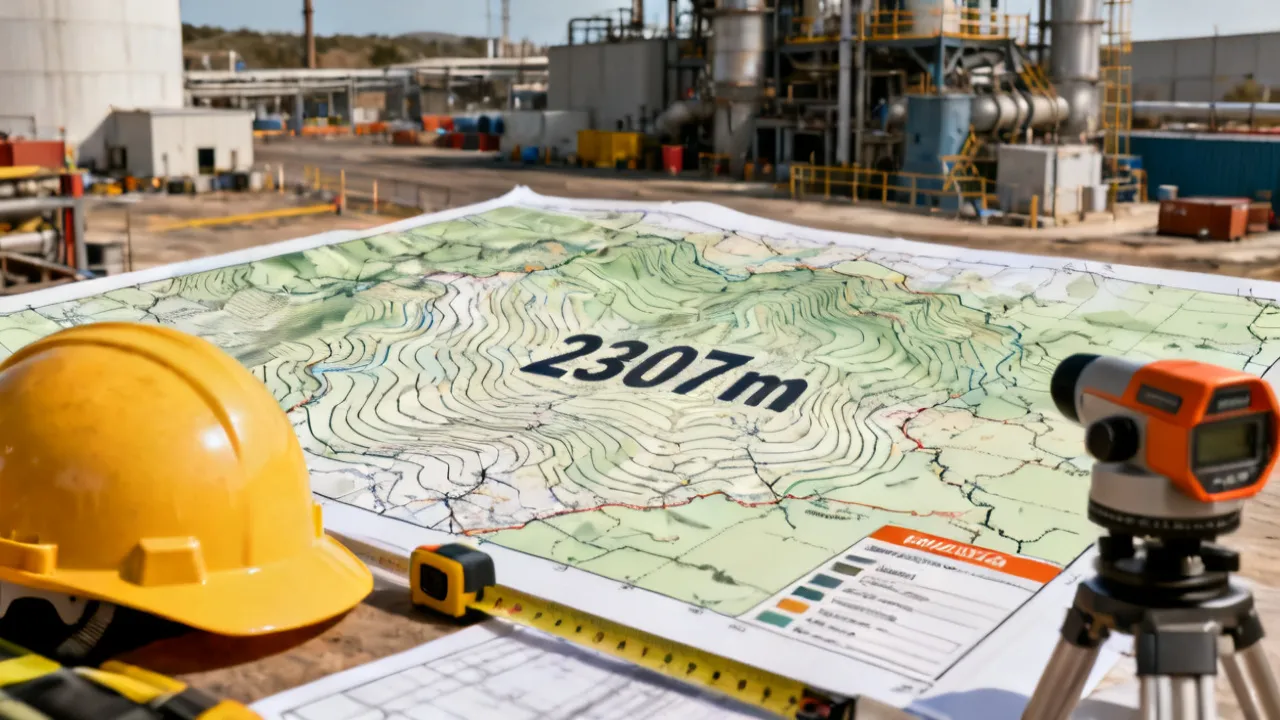
This guide explains how 2307m influences planning, measurement, compliance, and sourcing decisions across technical projects. It provides objective background on what 2307m typically represents in measurement contexts, why precision matters, and how suppliers and location-adjacent constraints can affect timelines and costs. Readers will find a comparison table, a step-by-step checklist, conditions, and FAQs for practical decision-making.
Esta guía analiza de forma objetiva el fenómeno del Porno en línea, su contexto cultural, riesgos y criterios de consumo responsable. Se revisan factores que influyen en la demanda (accesibilidad, hábitos y moderación de contenidos) y se explican señales de alerta asociadas a privacidad, seguridad y posible desinformación. El objetivo es ayudar a lectores a tomar decisiones informadas.
Esta guía aborda el tema “Porno” desde una perspectiva objetiva de alfabetización digital, privacidad y gestión de riesgos. Se explica qué significa el término en el contexto actual de consumo online, cómo se difunde el contenido adulto en internet y por qué conviene evaluar la fiabilidad de páginas y anuncios. También se ofrecen criterios prácticos para navegar con mayor control y seguridad.
Este artículo guía sobre cómo analizar el contenido adulto en línea con criterio, privacidad y seguridad. Se explica el contexto del término “Porno” como categoría de contenido, su impacto en hábitos digitales y los riesgos potenciales asociados a la desinformación, el consentimiento y la exposición no deseada, con enfoque preventivo y criterios de evaluación orientados a buenas prácticas.
Este artículo ofrece una guía objetiva para comprender el contenido adulto (“Porno”) desde una perspectiva de alfabetización digital y salud informativa. Se revisa el contexto del término, los riesgos habituales de consumo impulsivo, el impacto en la privacidad y cómo evaluar de forma crítica la oferta disponible. Además, se proponen criterios prácticos para tomar decisiones responsables y seguras.
Este artículo ofrece una guía objetiva para comprender el fenómeno del “Porno”, sus impactos, y las formas de reducir riesgos digitales. Se revisa el contexto histórico y social del contenido sexual en línea, su relación con algoritmos y hábitos de consumo, y las implicaciones de salud sexual, privacidad y bienestar. El objetivo es informar con criterios de prevención y uso responsable, sin promover conductas dañinas.

